Waymark - developing eval infrastructure for AI creative quality
At Waymark I was responsible not just for making the AI video quality better, but for knowing whether I actually had. Supporting that required a suite of internal testing tools I built using AI-assisted development, primarily Bolt and Replit, at a pace that would have been impossible through normal engineering cycles.
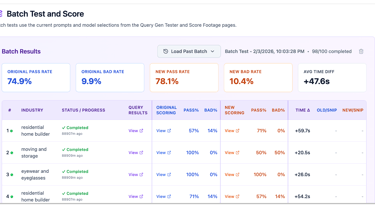
The toolset grew alongside the pipeline work: a footage search and scoring explorer, a query generation lab comparing production against in-development versions, batch processing across datasets of 100 or more real businesses, and purpose-built testers for color, image selection, and scriptwriting. Every tool shared the same architecture: the same auth pattern, the same model selector, the same prompt version management interface. Where the tools scored output automatically, I reviewed results myself to calibrate the scoring until I could rely on it.
COMPANY
Waymark
ROLE
Director of Product
BUILT WITH
Bolt, Replit
FOCUS
AI-assisted development
LLM evaluation
Product management
Team leadership


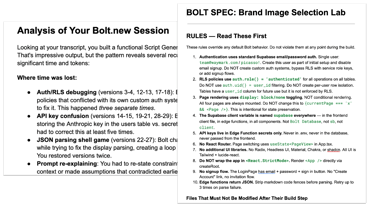

That consistency came from turning the development process itself into a system to optimize. After analyzing a transcript of one of my own early Bolt sessions, I found roughly 40-50% of iteration time was going to recurring failure patterns. I redesigned around a spec-first workflow with reusable boilerplate and structural patterns adapted per tool. Each subsequent tool launched faster than the last. Using AI to improve AI development is a compounding skill, and one that transfers regardless of which tools you're using.
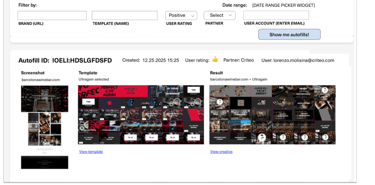
I conceived and spec'd two tools for engineering that shortcut the QA process. The Batch Generator creates scores of autofills from a URL list in minutes, making controlled before-and-after comparison possible at scale. The Autofill Snapshot tool let the team review videos frame by frame as a contact sheet, without having to watch each one. The Batch Generator cut about five minutes of QA time per video, roughly 500 minutes per 100-video run, and I used it to generate thousands of ads that the old process would have taken most of a year to produce.
No tool can fully replace human judgment on creative quality, so I also defined a nine-dimension rubric covering footage selection, color selection, image selection, text, script, logo, template selection, (lack of) cut-off faces, and overall brand fit, each scored on a four-point scale from TV-ready to reject and redo. The Autofill Voting Station distributed this across the team, managing weekly review runs and aggregating scores by category. The voting started in a spreadsheet, and I built the app once the process had proved itself. Reviewers picked the biggest problems out of the nine dimensions and rated how bad each was, so the report showed both how widespread and how severe each issue was. In the final weeks, seven reviewers were scoring twenty or more videos per run, using test runs that took me 10 minutes to set up.

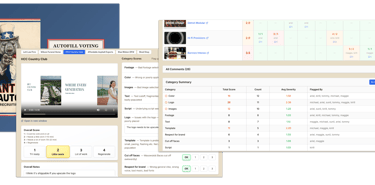
The data was actionable in both directions: when color and logo issues topped the rankings, that directed the next round of work. When footage flags dropped after the pipeline shipped, that confirmed the improvement was real.
Taken together, this gave us a way to improve quality quickly and prove each improvement with data.